AI Computing Infrastructure

Building the Foundation
of the AI Era

High-performance GPU clusters · Intelligent elastic scheduling · Extreme inference acceleration
Rebuilding AI compute from the ground up — efficient, reliable, and infinitely scalable.

About Si

Si is a technology company focused on AI computing infrastructure. We build high-performance, highly available, and elastically scalable AI compute foundations, delivering end-to-end solutions from training to inference for enterprises and developers.

In the era of large models and multimodal AI, compute has become a core production factor. Through our proprietary scheduling system, liquid-cooled high-density clusters, and deeply optimized software stack, Si helps customers improve compute utilization by 30%+ while significantly reducing energy consumption and operational complexity.

We believe true AI infrastructure is not just about stacking GPUs — it is an intelligent, reliable, and future-ready computing foundation.
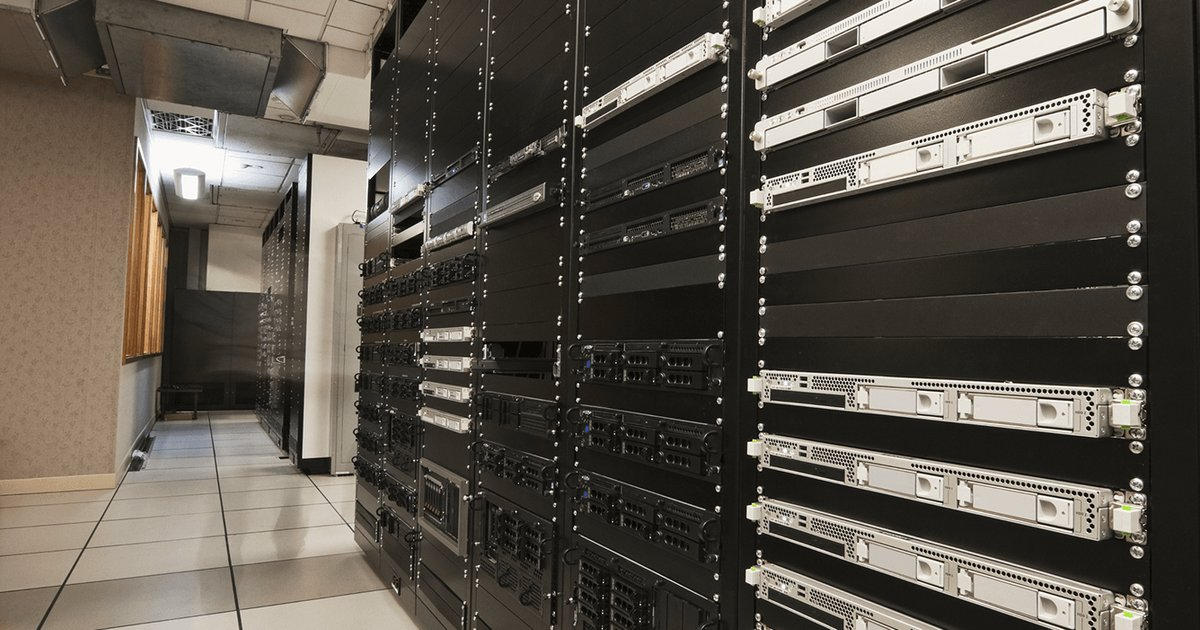
High-performance AI compute cluster

Core Capabilities

A complete AI compute stack from hardware to software

⚡

High-Performance GPU Clusters

Support for the latest H100/H200/B200 and domestic AI chips. High-density liquid-cooled deployment, scalable to tens of thousands of GPUs per cluster.

🔄

Intelligent Elastic Scheduling

Proprietary scheduling engine with multi-tenant isolation, priority queues, and auto-scaling. Industry-leading compute utilization.

🚀

Inference Acceleration Engine

Deeply optimized inference stack supporting vLLM, TensorRT-LLM and more. Latency reduced by 40%+.

🔒

Security & Isolation

Hardware-level isolation, encrypted transport, and compliance auditing — built for finance, government, and other sensitive workloads.

📊

Observability Platform

Full-stack monitoring, performance analysis, and cost attribution. Complete visibility into every compute resource.

🌐

Open-Source Compatible

Seamless compatibility with CUDA, Kubernetes, PyTorch, JAX and the broader ecosystem. Zero migration cost.

Technical Architecture

Layered design — a complete AI compute stack from hardware to applications

5

Application & Model Layer

Large model training, fine-tuning, inference serving, multimodal applications

4

AI Framework & Acceleration Layer

PyTorch / JAX optimization, inference engines, compiler optimizations

3

Scheduling & Orchestration Layer

Intelligent scheduling, multi-tenant isolation, elastic scaling, job queues

2

Container & Runtime Layer

Kubernetes, container runtime, network and storage virtualization

1

Hardware & Infrastructure Layer

GPU/ASIC clusters, liquid cooling, high-speed interconnect, power and networking

99.99%
Cluster Availability
30%+
Utilization Improvement
100K+
GPUs Under Management
<5ms
Scheduling Latency

Ready to Build Your AI Compute Foundation?

Talk to our architecture team for a tailored solution and POC demo.

Contact Us